This week, the cost math finally caught up with the frontier. Z.AI, Alibaba, and Tencent all shipped big Mixture-of-Experts systems that activate only a sliver of their parameters per token, while Google pushed Gemini toward true agentic video understanding. The through-line: more capability on a dramatically smaller compute and price footprint. Here's what landed and what it means.
The launches that reset the pricing math
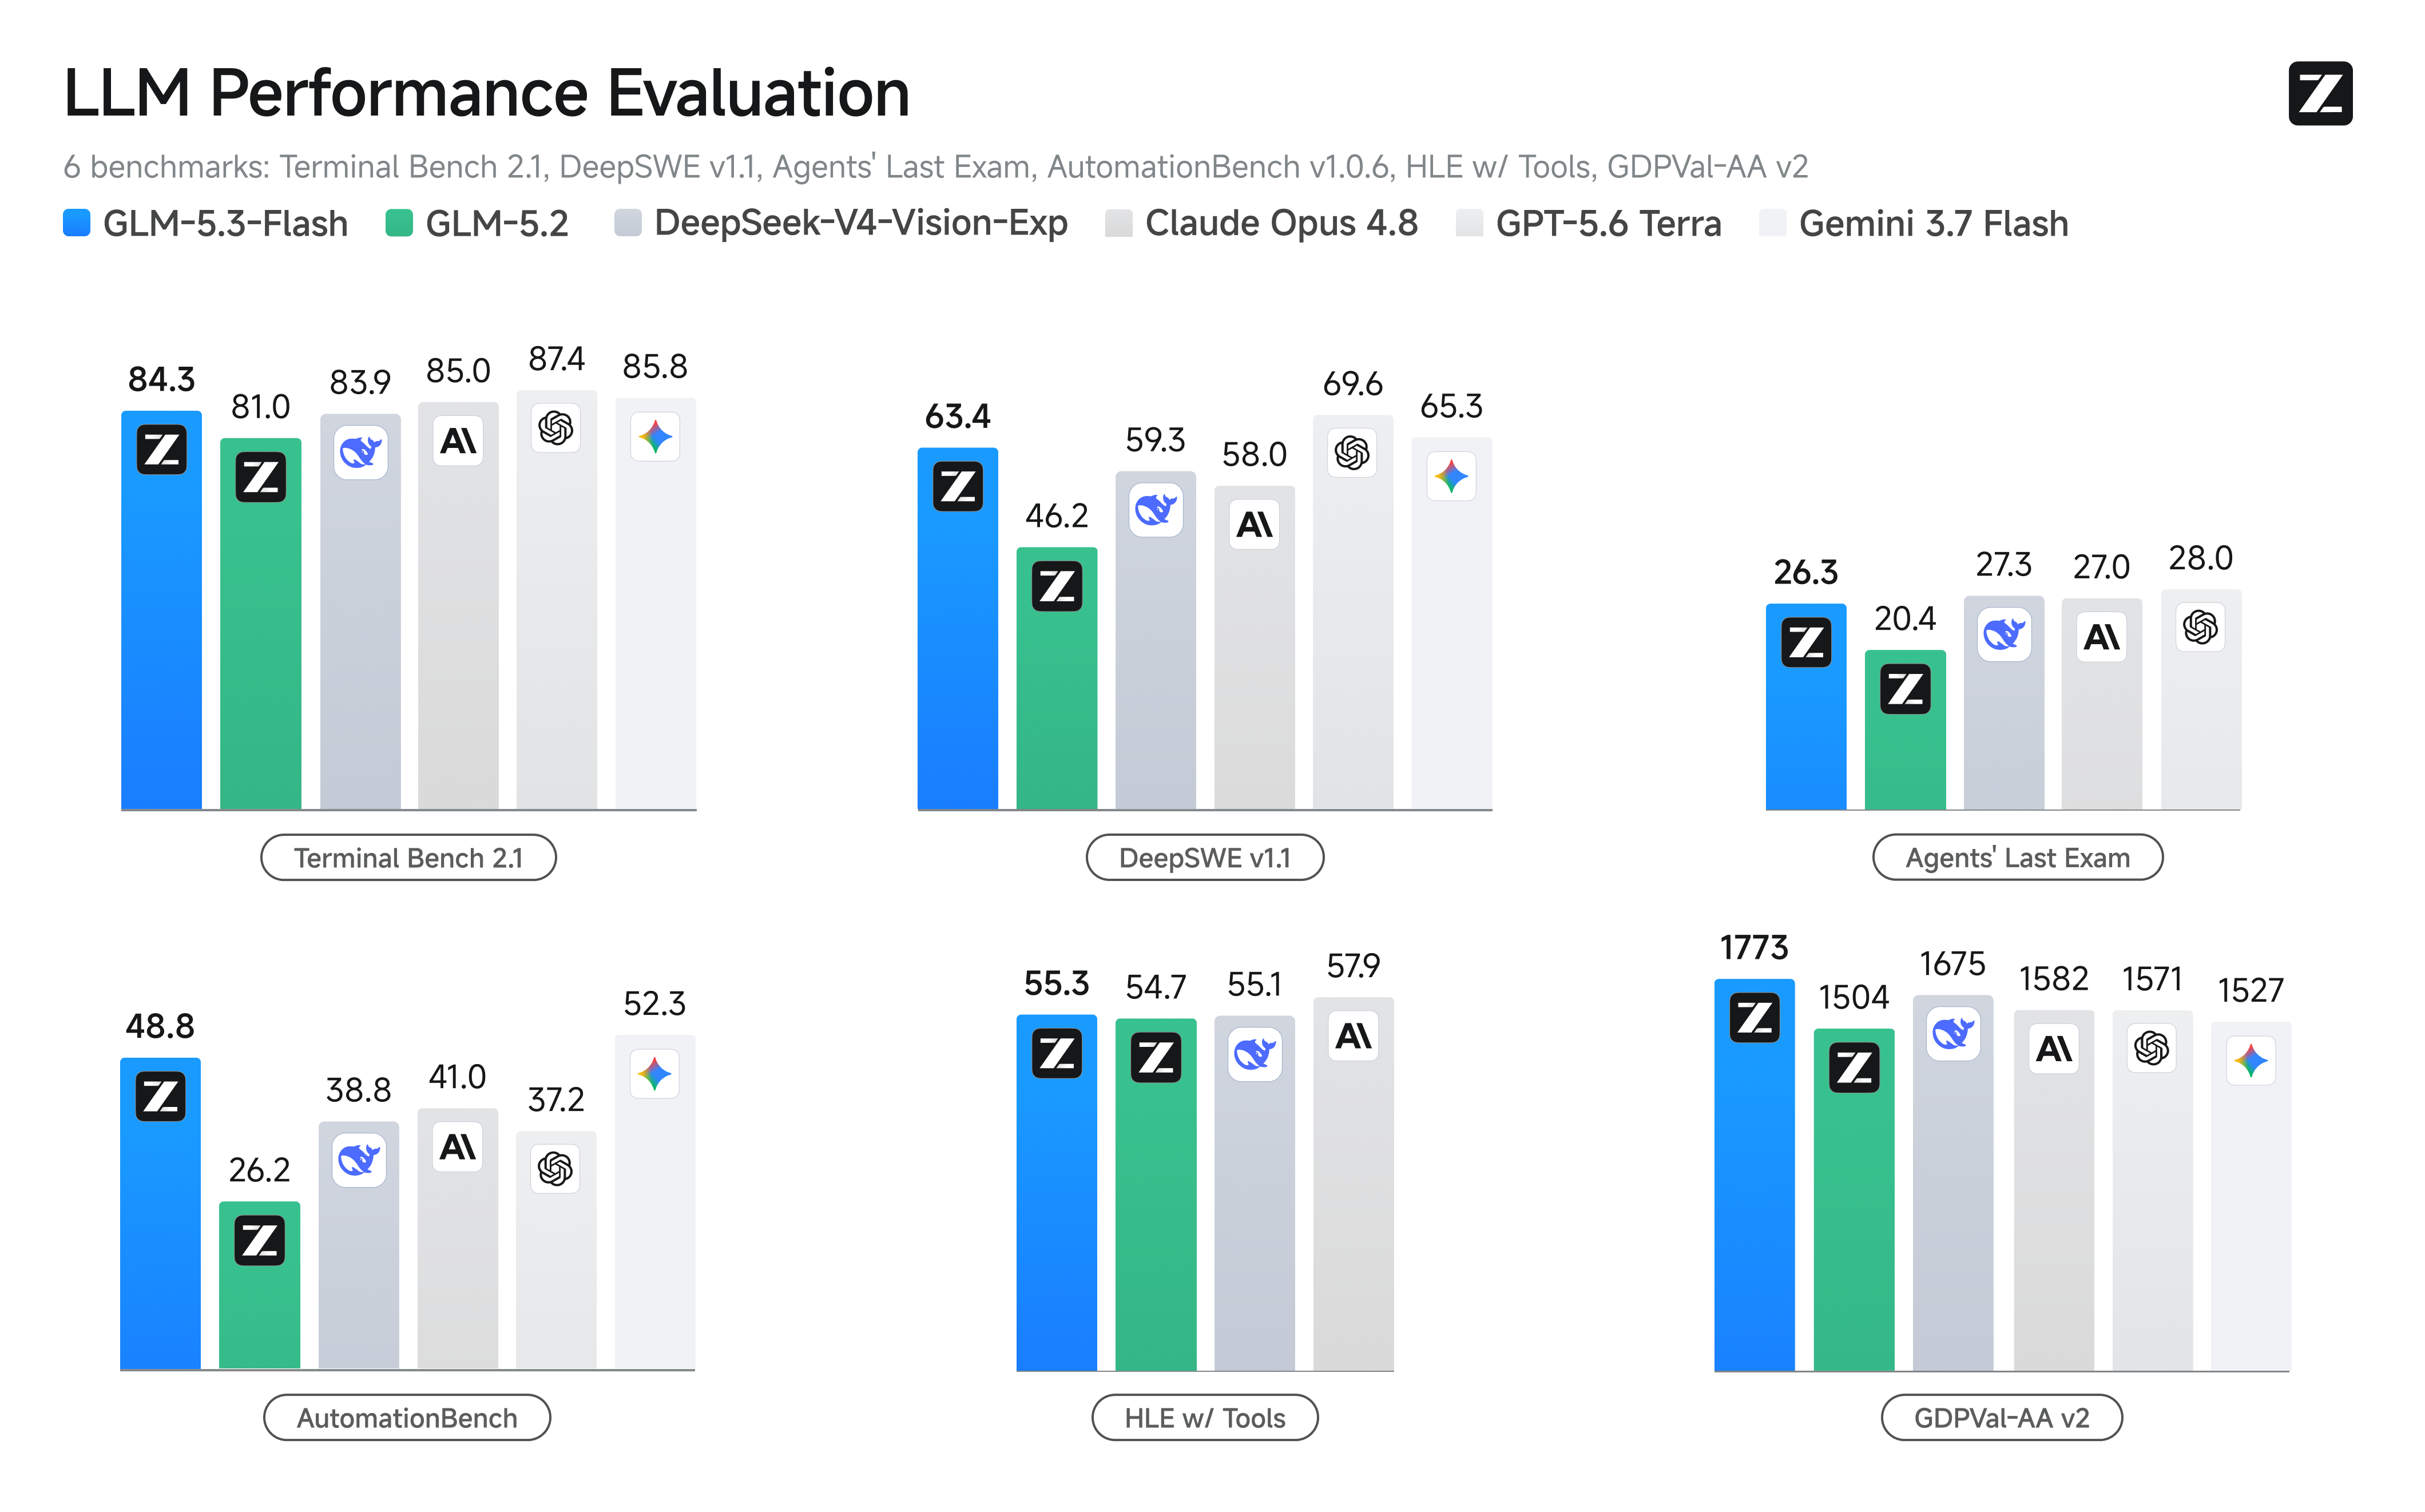
GLM-5.3-Flash runs 320B total parameters with only 18B active per token, pairing hybrid sparse and linear attention with vision and a 1M-token context window. Released under an MIT license, it's positioned as a much cheaper alternative to closed frontiers for demanding coding and agent workloads. Z.AI has also folded GLM-5.3 into its ZCode harness and a $18/month coding plan. Read more →
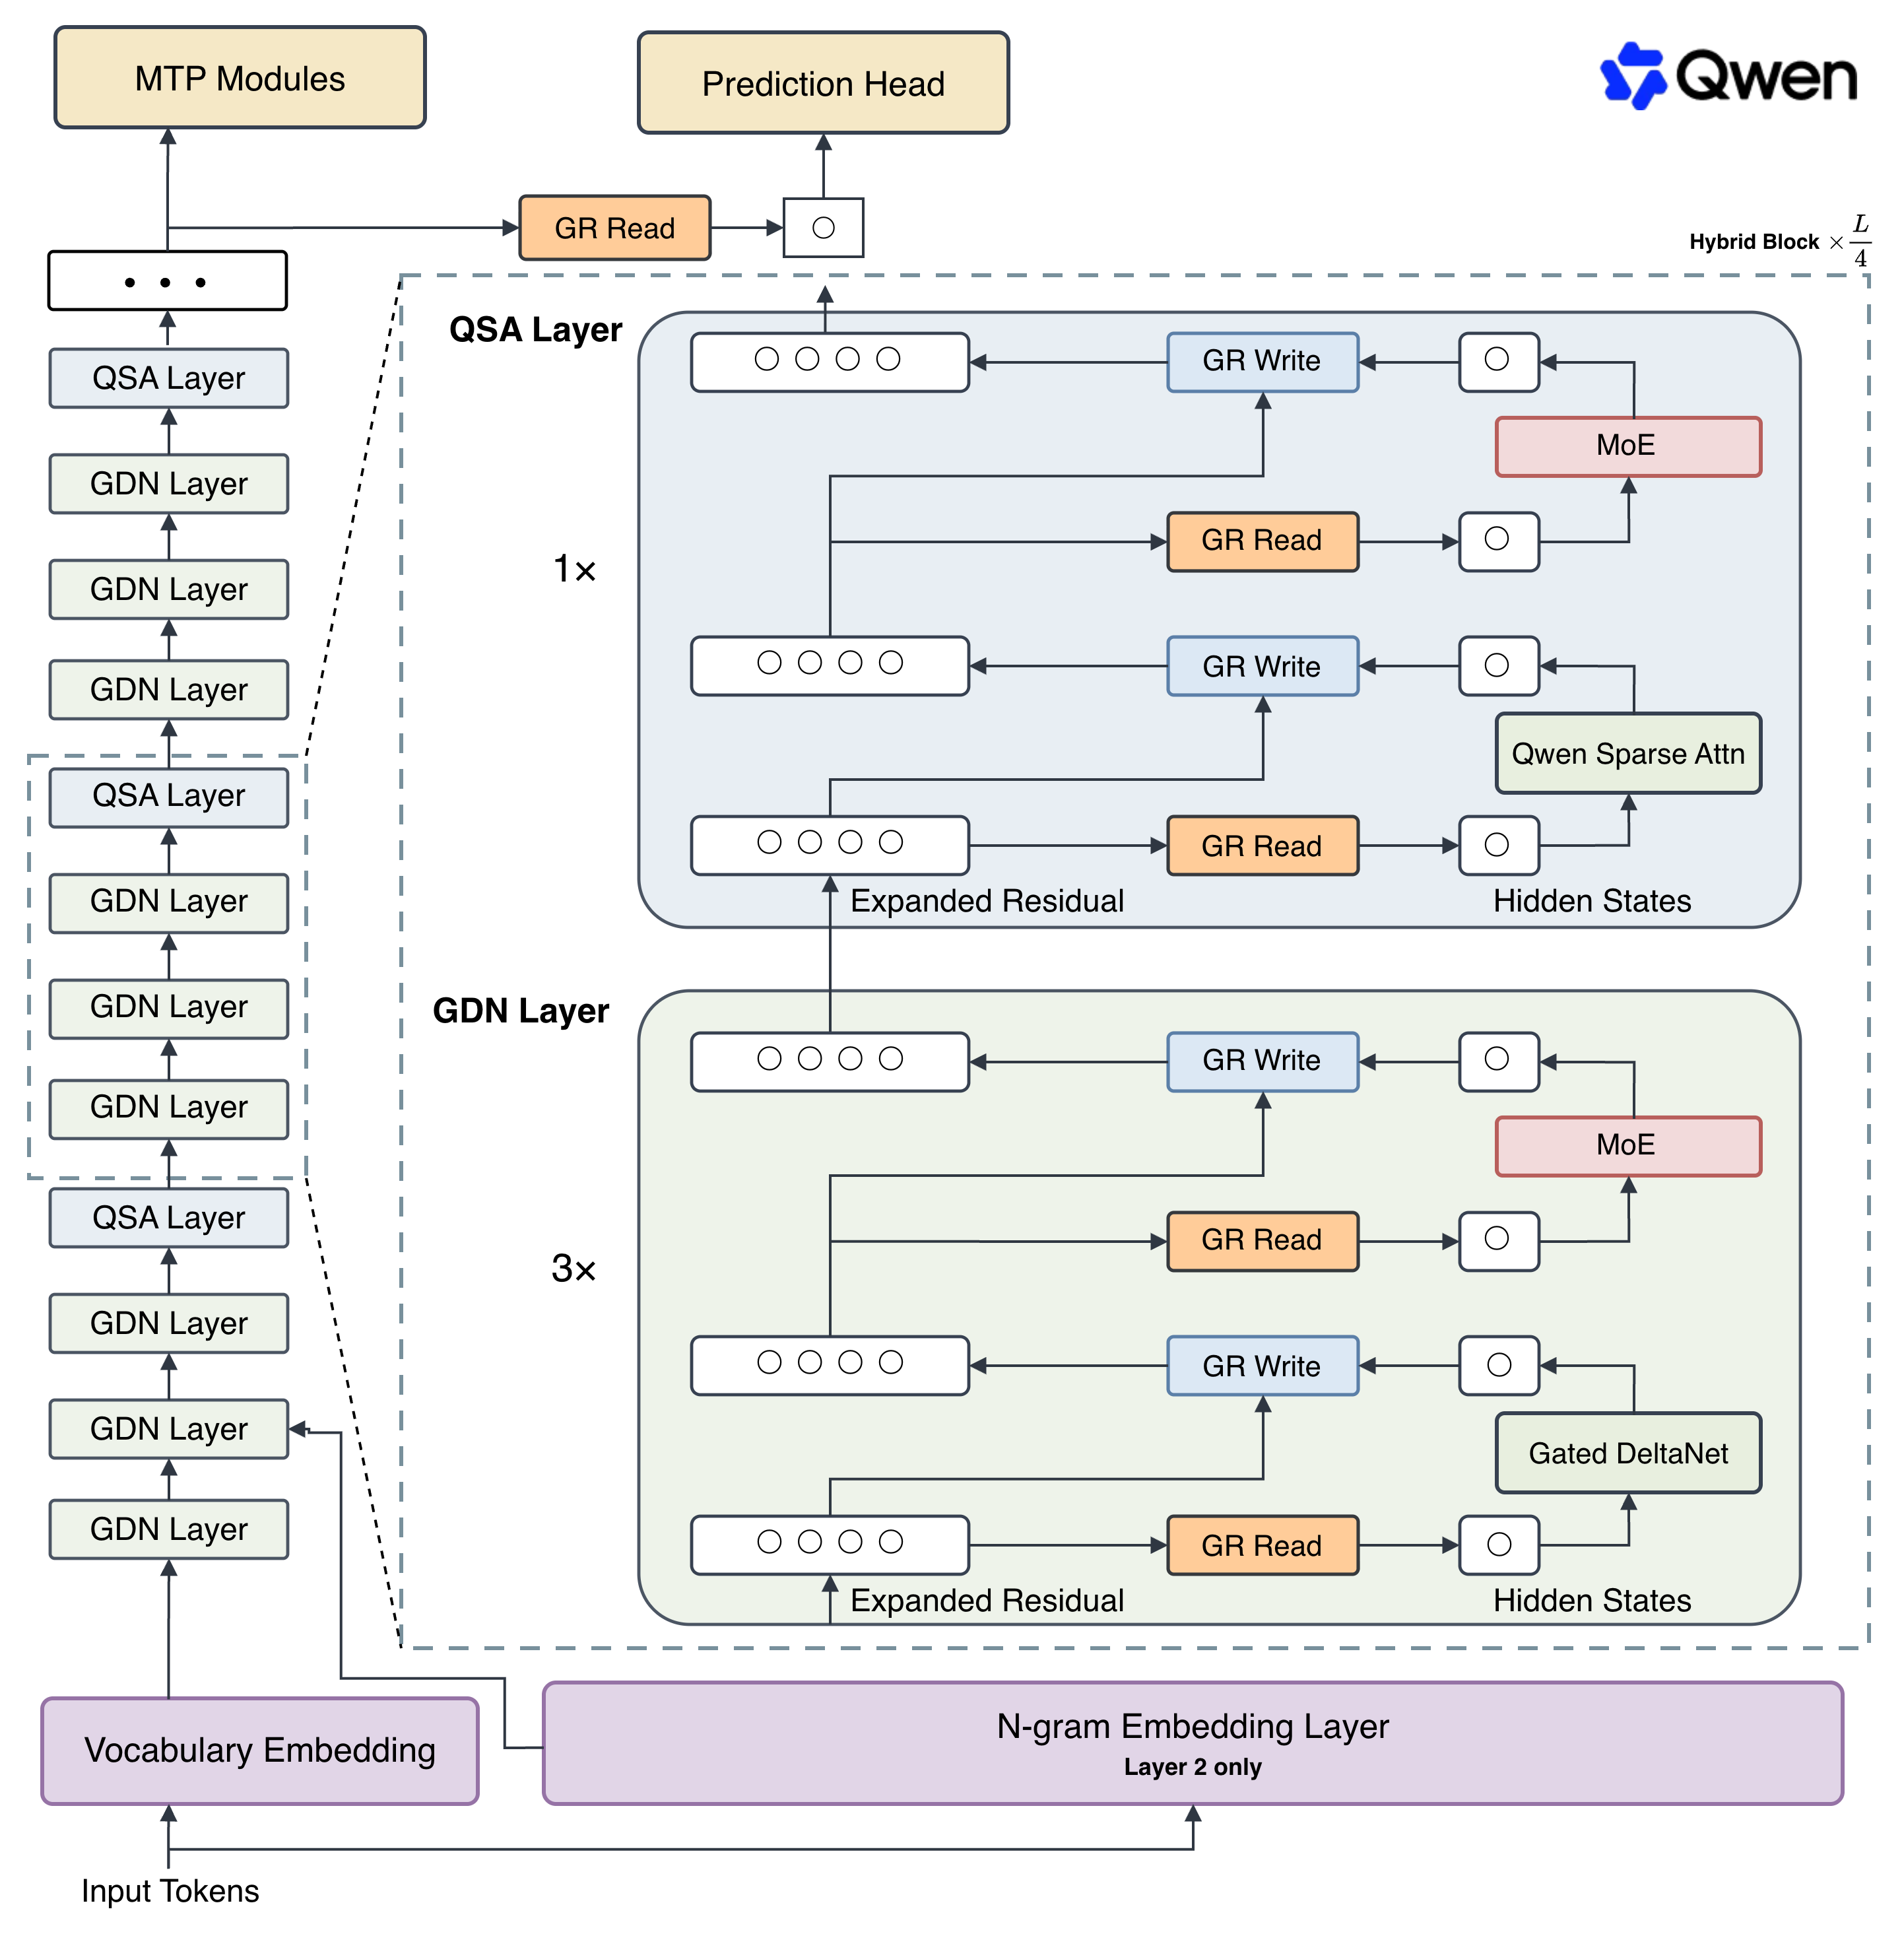
Qwen3.8-Flash-Next activates just 6B of its 125B total parameters, previewing the qwen4_exp architecture Alibaba says will underpin Qwen4. It serves a native 262,144-token context that extends to 1M via the managed Qwen3.8-Flash API, shipping as open weights. GGUF quantisations are already trending on Hugging Face, which makes it a realistic local workhorse. Read more →

Tencent Hy4-preview is a 770B-parameter open MoE with 49B active and a context window beyond 1M tokens, released under Apache-2.0. The Hugging Face drop targets hard coding, office, game, and research workloads, shipping vLLM and SGLang deployment recipes. It's one of the largest permissively-licensed systems of the cycle. Read more →
Agentic video and cheaper tokens
Gemini 3.7's new agentic video understanding pinpoints sub-second events and answers complex questions across multi-hour videos using far fewer tokens than static analysis. Google positions it as token-efficient long-form video understanding with dynamic-FPS resampling, available across Gemini 3.7 Flash, 3.6 Flash, and 3.5 Flash-Lite at standard token pricing. The implications for automated editing and archival search are immediate. Read more →
The average cost per million LLM tokens has fallen to 97 cents, down sharply from a $2.07 high on May 28. The LLM Token Expenditure Index tracks a months-long decline driven by the same sparsity playbook as above — flash-tier MoEs that ship frontier-quality results at a fraction of the price. (via CNBC, aggregated on the live LLM Stats feed.) Read more →

LTX-2.5 from Lightricks is a 22B open-weights model that generates synchronised video and audio from text, image, or video input in a single pass. It adds native multi-shot scenes, auto duration, and 4K HDR output with day-one ComfyUI templates, and runs locally on a 24GB card. Read more →

DeepSeek-V4-Flash-Vision-Exp adds vision input to the V4-Flash family, letting developers pass images through the same API endpoints they already use for text. It's an experimental model (MIT) that strengthens DeepSeek's multimodal agent stack without a separate API surface. Read more →
That is the issue
If you want the full index with model cards and benchmark tables, it lives on the After Intelligence site; this newsletter is the fast path.
Subscribe to get tomorrow's briefs in your inbox before they hit the web.